Memory Helps Autonomous Driving
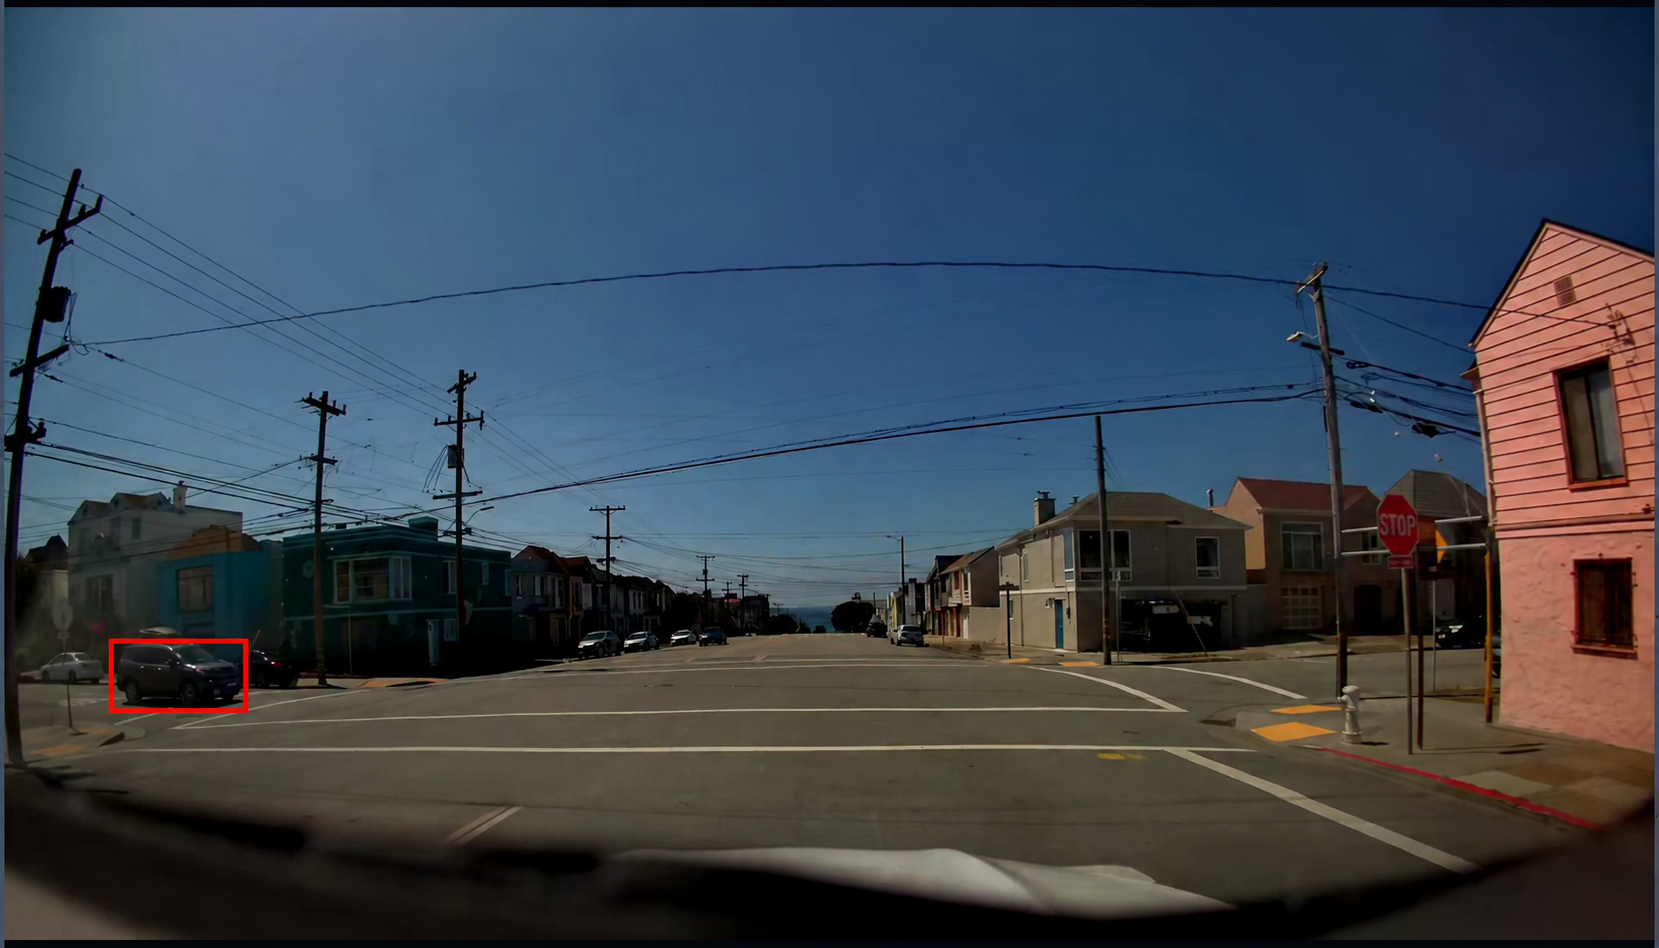
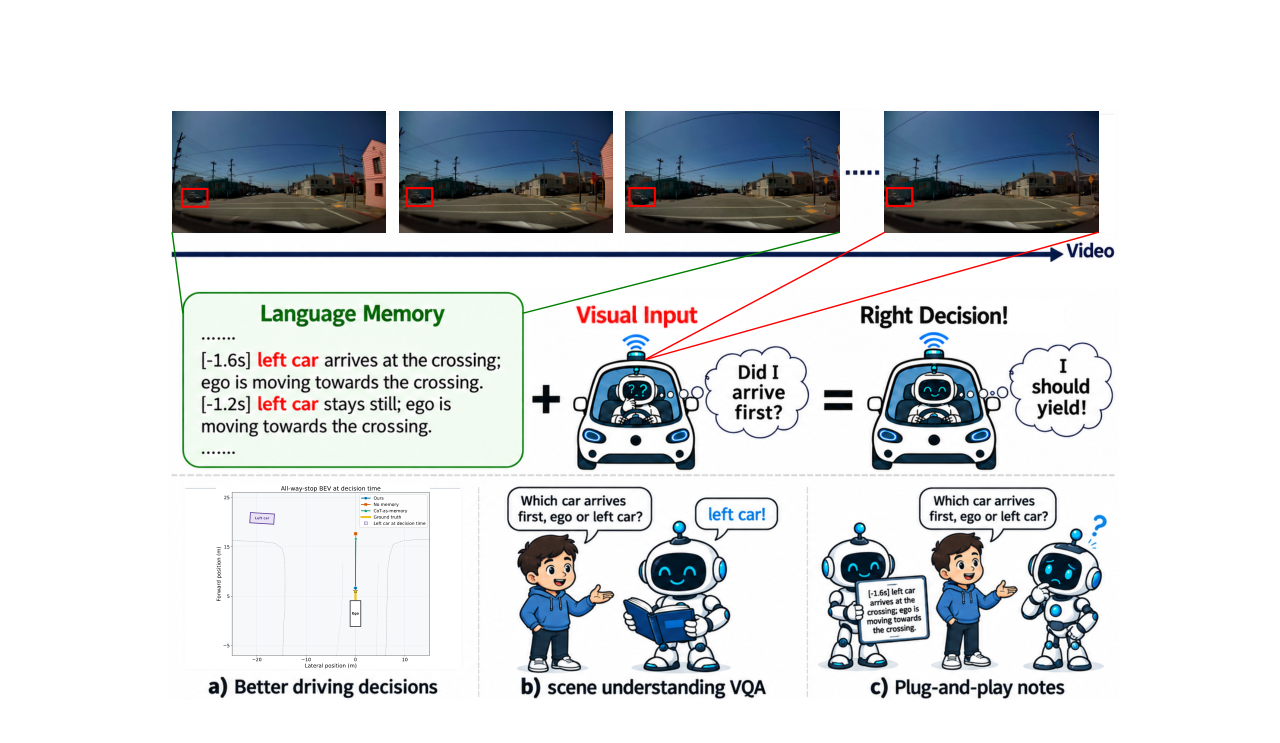
VLA agents cannot take too many frames as input due to the high token cost of images. Thus, the current image input can be ambiguous when the relevant evidence appeared only seconds earlier. Below shows example of how memory can help the agent make the right driving decision.
Click to see how memory helps
AD-Memo: Autonomous Driving with Language-Based Memory
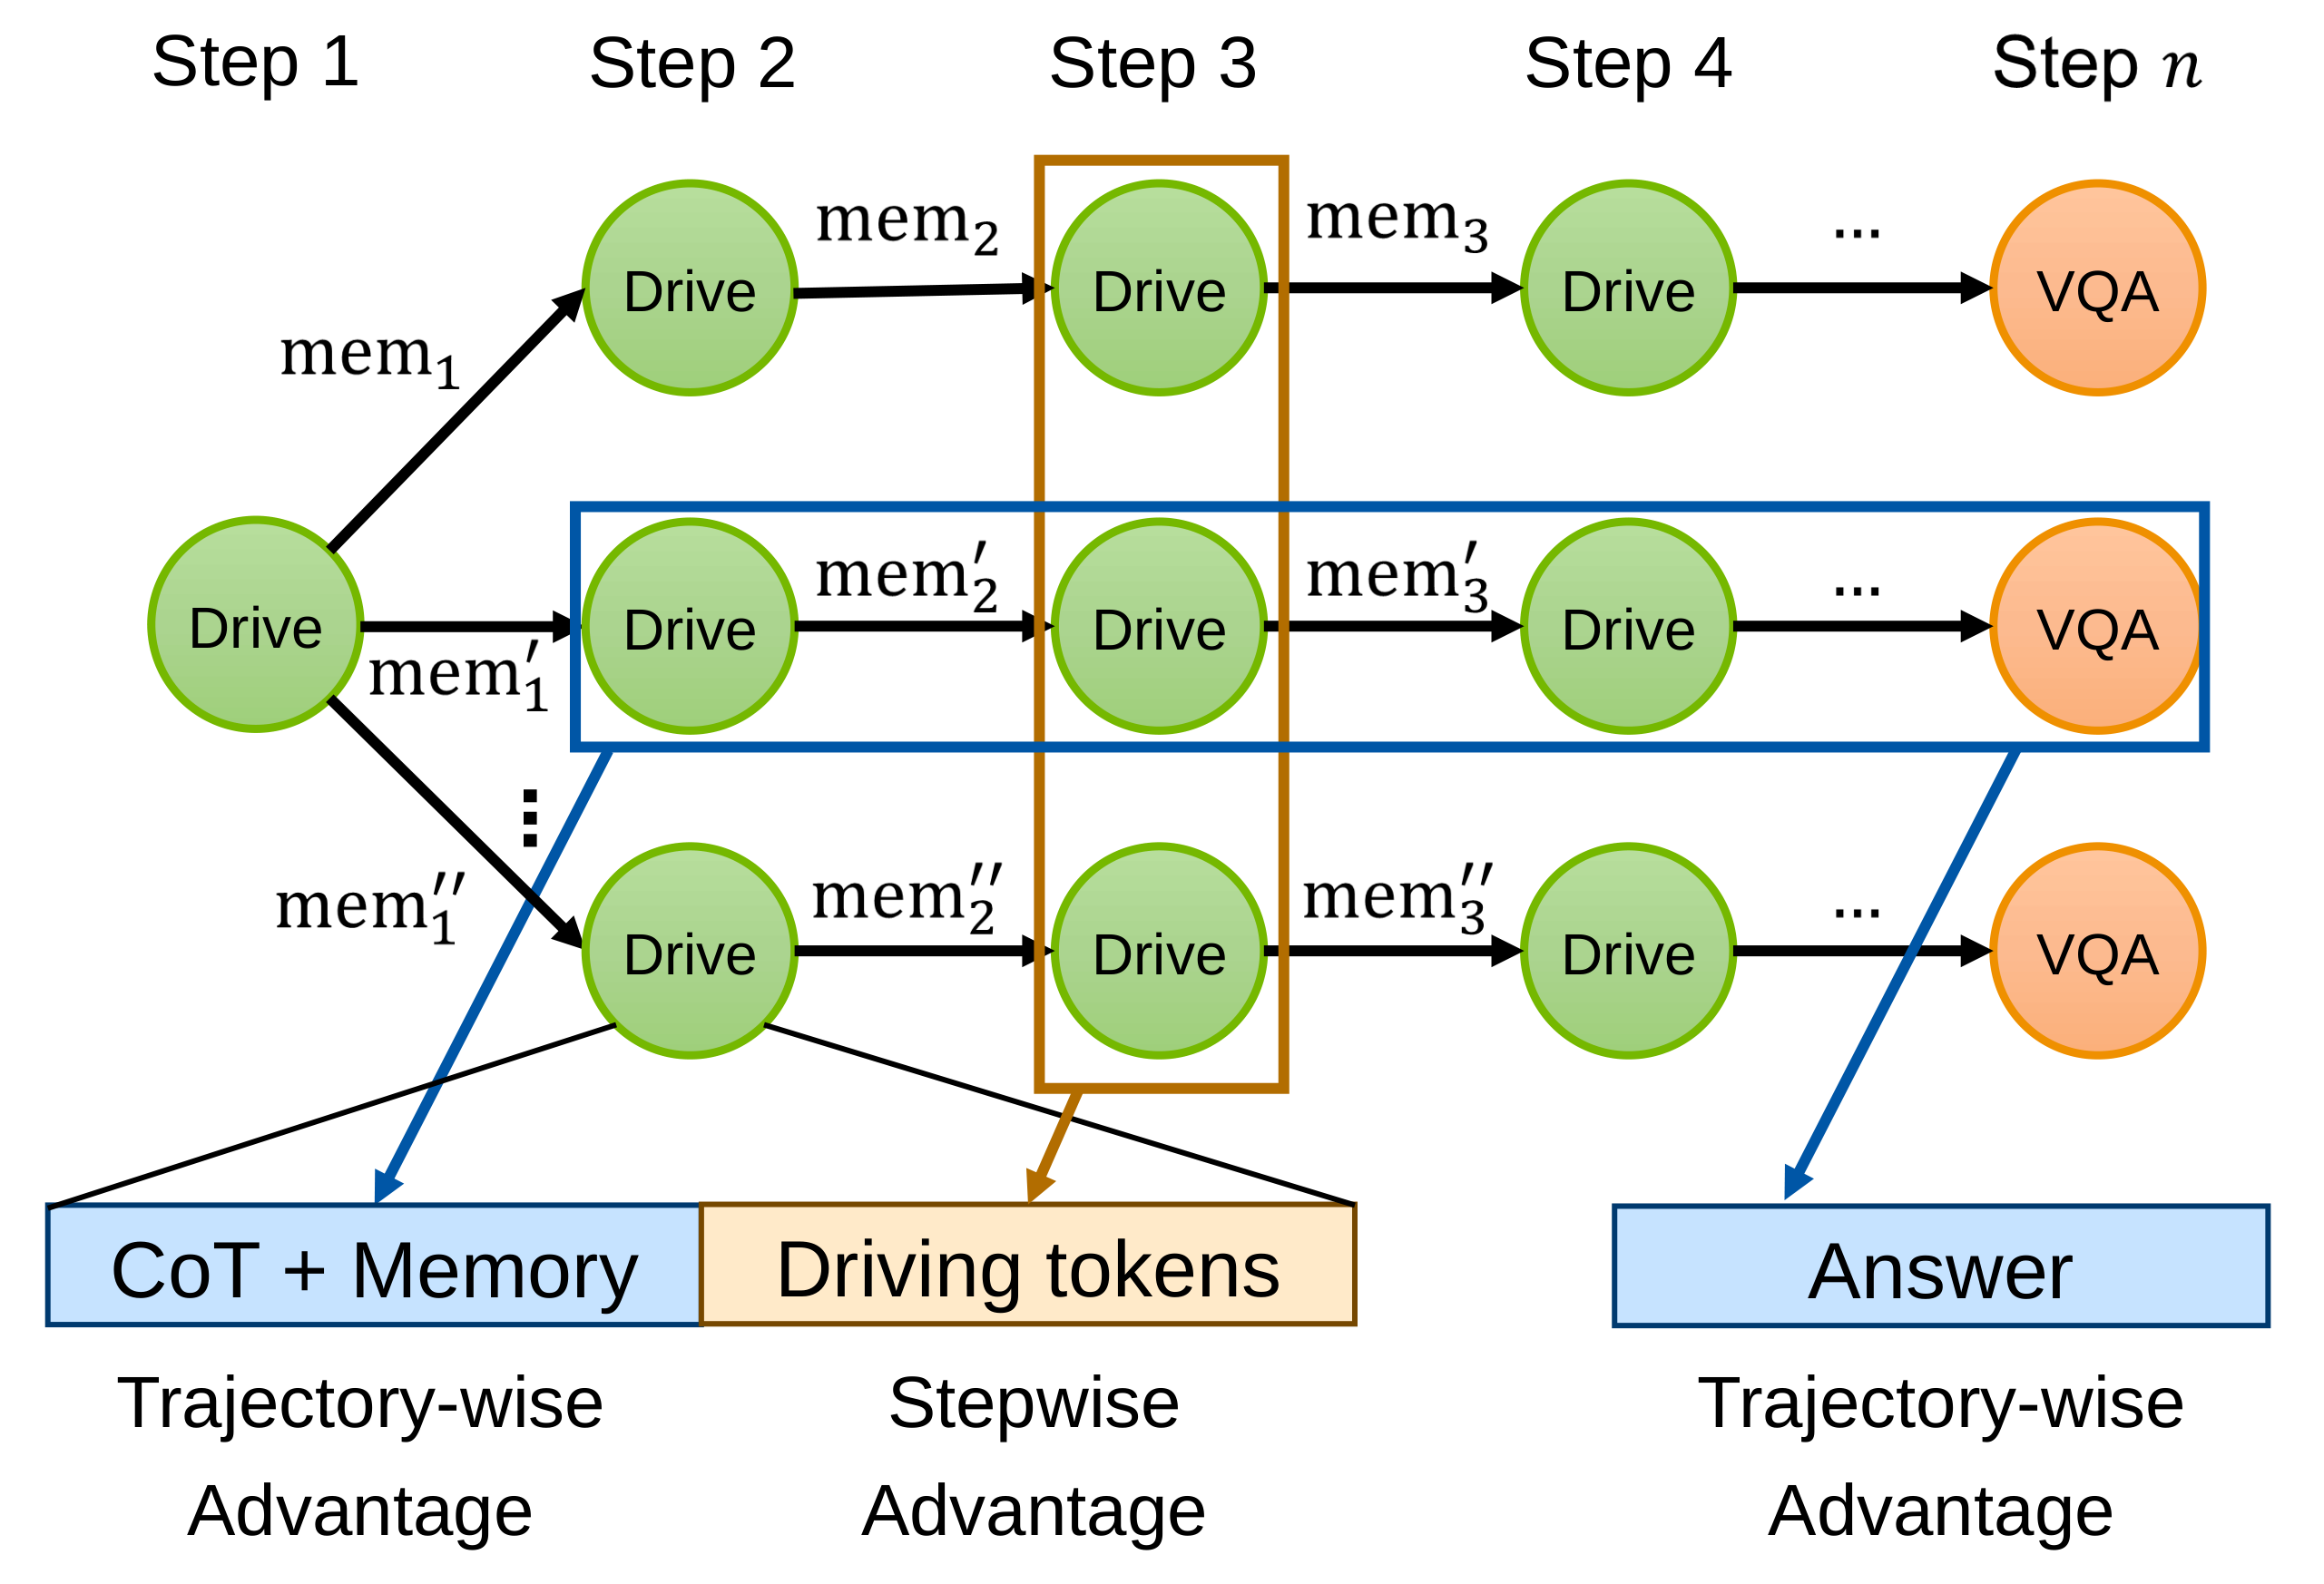
AD-Memo is a streaming video agent switching between two modes: driving and VQA. We divide a video by visual input horizon t, and consider the n+1 "keyframes" each separated by t; in keyframe 1 to n, the agent is in driving mode, generates trajectories and language memory. The memory becomes part of the agent's future input. At keyframe n+1, the agent switches to VQA mode and answers question based on the memory.
Memory is emitted as an extension of Chain-of-Thought. A rolling window of previous entries becomes language input at the next keyframe, while the model continues to produce its 6.4-second driving trajectory.
Driving and VQA Mode
The idea of appending VQA at the end of the video is that, by asking a question on critical objects that affects driving, the agent must remember every critical object to answer the question correctly as it does not know what the question will be during driving. When deployed, the VQA mode will never be activated, but the agent will still generate relevant memory. VQA is also a good way to evaluate the effectiveness of the agent's memory.
BriefTracks only the decision-relevant objects of every past frame.
ExplainableExposes what the agent retained in a human-readable way, fully exploiting VLM backbone reasoning capabilities.
PortableCan be passed to another model without architecture-specific memory modules.
Da Capo: Semi-Closed-Loop Reinforcement Learning

Supervised training never exposes the model to its own imperfect memory. Da Capo addresses this exposure bias without requiring an expensive, fully interactive driving simulator.
Open-loop in control, closed-loop in memory
Across K parallel rollouts, visual observations and past ego trajectories are replayed from ground truth. Each rollout nevertheless consumes the memories it generated at preceding steps.
Different Advantages for Heterogeneous Tokens
Driving tokens in open-loop control are conditionally independent from future rollouts, but memory tokens must receive reward signals from future; to address this heterogeneity, we propose Deviation-Adjusted Causal Advantage Policy Optimization (Da Capo) for better credit assignment.
- Driving tokens: receive only stepwise advantage as a predicted trajectory does not alter later replayed states.
- Memory tokens: receive future-dependent advantage from downstream driving and terminal VQA rewards.
- Deviation adjustment: standard-deviation normalization balances heterogeneous reward scales.
How to Curate Driving-Critical Memory?
We curate two datasets: all-way stop and general driving. For the former, object of interest are the cars in the crossing and thus we can generate rule-based memory; for the latter, we need to identify objects that really affects driving decisions.
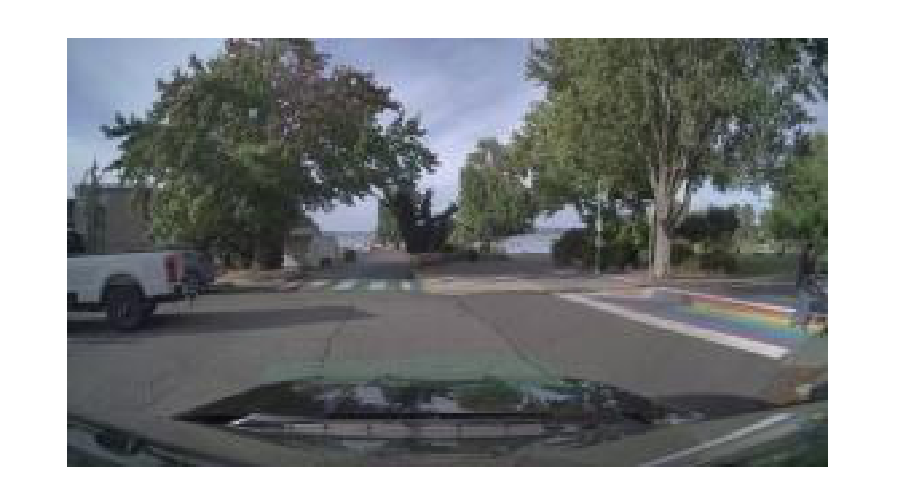
Original front-camera observation.
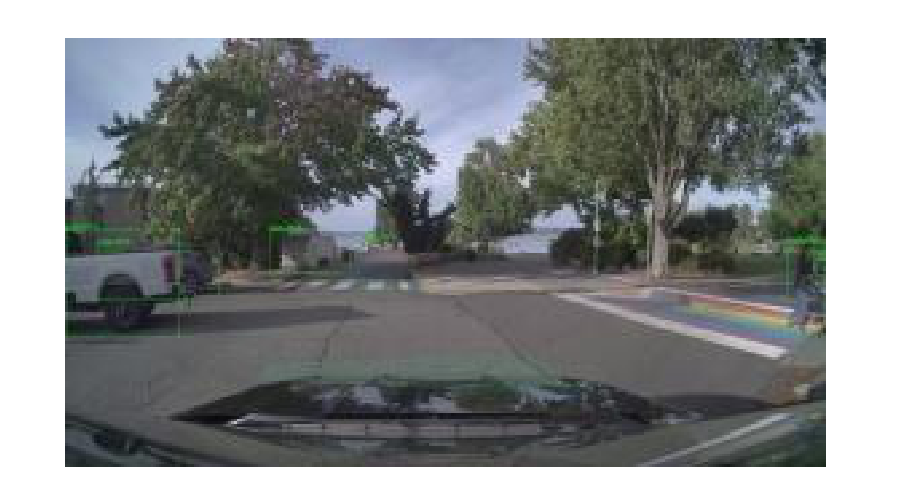
Driving-relevant actors, map elements, and traffic rules are grounded in the image.
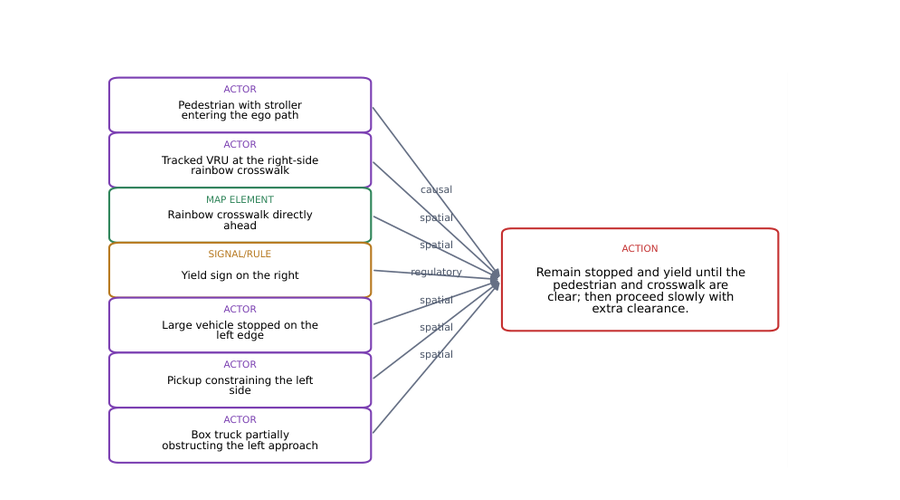
Evidence nodes connect to the calibrated ego action through causal, spatial, and regulatory relations.
Decision graphs keep memory relevant.
Describing every visible object would make language memory long and distracting. We curate a novel agentic pipeline that builds a decision graph, which identifies which grounded entities actually affect the expert action.
Memory is generated from action-connected nodes and then merged across the clip to preserve stable references and temporal continuity.
Experimental Results
The tables below reports the main results reported in the paper. ↓ indicates lower is better; ↑ indicates higher is better.
All-Way Stop
All-way stop dataset serves as a task-specific evaluation where we know memory are important and know what memory are needed.Table 1. Results on 2,479 test clips and 50,533 keyframes. “Ref. mem” uses reference memory generated in the same way as SFT labels. ML. = Most Likely, SR = Success Rate, Δpos = Position Difference, Δdur = Duration Difference, Roll = Roll-through Rate, and MCQ = Multiple Choice Question Accuracy.
| Model | minADE ↓ | Avg. ADE ↓ | ML. ADE ↓ | Stop SR ↑ | Go SR ↑ | Δpos ↓ | Δdur ↓ | Roll ↓ | MCQ Acc. ↑ |
|---|---|---|---|---|---|---|---|---|---|
| Base Model | 1.386 | 2.351 | 2.393 | 82.06% | 33.74% | 1.725 | 1.871 | 11.79% | 0% |
| Alpamayo 2 Super 34B | 0.993 | 2.293 | N/A | 78.75% | 34.30% | 2.182 | 1.488 | 15.94% | 33.19% |
| No mem. (SFT only) | 1.102 | 2.185 | 2.318 | 87.04% | 38.59% | 1.358 | 1.564 | 6.62% | 33.77% |
| CoT mem. (SFT only) | 1.096 | 2.171 | 2.296 | 86.89% | 39.37% | 1.377 | 1.531 | 6.69% | 45.41% |
| AD-Memo (SFT only) | 1.049 | 2.121 | 2.256 | 87.48% | 40.66% | 1.257 | 1.469 | 6.05% | 45.99% |
| CoT mem. (SFT + ref. mem) | 1.098 | 2.169 | 2.286 | 86.95% | 39.45% | 1.367 | 1.521 | 6.61% | 45.24% |
| AD-Memo (SFT + ref. mem) | 0.963 | 1.963 | 2.086 | 87.70% | 44.66% | 1.185 | 1.296 | 5.84% | 89.53% |
| No mem. (SFT + Da Capo) | 0.944 | 1.952 | 2.005 | 88.92% | 43.76% | 1.125 | 1.248 | 5.21% | 35.32% |
| CoT mem. (SFT + Da Capo) | 0.968 | 1.906 | 1.942 | 89.20% | 44.88% | 1.157 | 1.194 | 5.31% | 45.87% |
| AD-Memo (Ours) | 0.951 | 1.866 | 1.915 | 89.26% | 45.01% | 1.070 | 1.183 | 5.26% | 51.66% |
General Driving
General driving tests the agent's ability to generalize to diverse driving scenarios.Table 2. Results on 9,112 test clips and 145,462 keyframes. Corner = Corner distance.
| Model | minADE ↓ | Avg. ADE ↓ | ML. ADE ↓ | minFDE ↓ | Avg. FDE ↓ | ML. FDE ↓ | Corner ↓ | MCQ Acc. ↑ |
|---|---|---|---|---|---|---|---|---|
| Base Model | 1.032 | 1.981 | 2.049 | 2.853 | 5.937 | 6.194 | 1.001 | 0% |
| Alpamayo 2 Super 34B | 0.954 | 2.081 | N/A | 2.556 | 6.141 | N/A | 0.902 | 25.71% |
| No mem. (SFT only) | 1.007 | 2.033 | 2.075 | 2.716 | 6.108 | 6.279 | 0.968 | 58.02% |
| CoT mem. (SFT only) | 1.031 | 2.059 | 2.105 | 2.787 | 6.192 | 6.375 | 0.993 | 57.51% |
| AD-Memo (SFT only) | 1.005 | 2.011 | 2.049 | 2.705 | 6.042 | 6.196 | 0.967 | 65.63% |
| CoT mem. (SFT + ref. mem) | 1.034 | 2.064 | 2.105 | 2.795 | 6.207 | 6.373 | 0.995 | 57.36% |
| AD-Memo (SFT + ref. mem) | 1.012 | 2.014 | 2.051 | 2.734 | 6.053 | 6.208 | 0.974 | 67.65% |
| No mem. (SFT + Da Capo) | 1.090 | 1.883 | 1.891 | 3.042 | 5.583 | 5.648 | 1.062 | 57.43% |
| CoT mem. (SFT + Da Capo) | 1.105 | 1.907 | 1.918 | 3.071 | 5.631 | 5.707 | 1.079 | 56.94% |
| AD-Memo (Ours) | 1.091 | 1.864 | 1.869 | 3.027 | 5.512 | 5.576 | 1.066 | 65.51% |
Memory Portability
AD-Memo is special for its portability of the memory: it can be used by other models in a plug-and-play, 0-shot manner.Table 3. Accuracy of GPT-5.6 Luna on LingoQA and WaymoQA using AD-Memo's generated memory.
| Benchmark | Our memory + last frame | Only last frame | Full video |
|---|---|---|---|
| WaymoQA | 71.65% | 66.63% | 75% |
| LingoQA | 67% | 62.6% | 70% |